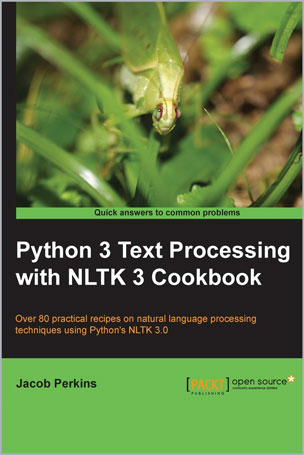
Over 80 practical recipes on natural language processing techniques using Python’s NLTK 3.0
About This Book
- Break text down into its component parts for spelling correction, feature extraction, and phrase transformation
- Learn how to do custom sentiment analysis and named entity recognition
- Work through the natural language processing concepts with simple and easy-to-follow programming recipes
In Detail
This book will show you the essential techniques of text and language processing. Starting with tokenization, stemming, and the WordNet dictionary, you’ll progress to part-of-speech tagging, phrase chunking, and named entity recognition. You’ll learn how various text corpora are organized, as well as how to create your own custom corpus. Then, you’ll move onto text classification with a focus on sentiment analysis. And because NLP can be computationally expensive on large bodies of text, you’ll try a few methods for distributed text processing. Finally, you’ll be introduced to a number of other small but complementary Python libraries for text analysis, cleaning, and parsing.
This cookbook provides simple, straightforward examples so you can quickly learn text processing with Python and NLTK.
What You Will Learn
- Tokenize text into sentences, and sentences into words
- Look up words in the WordNet dictionary
- Apply spelling correction and word replacement
- Access the built-in text corpora and create your own custom corpus
- Tag words with parts of speech
- Chunk phrases and recognize named entities
- Grammatically transform phrases and chunks
- Classify text and perform sentiment analysis
Table of Contents
Chapter 1: Tokenizing Text and WordNet Basics
Chapter 2: Replacing and Correcting Words
Chapter 3: Creating Custom Corpora
Chapter 4: Part-of-speech Tagging
Chapter 5: Extracting Chunks
Chapter 6: Transforming Chunks and Trees
Chapter 7: Text Classification
Chapter 8: Distributed Processing and Handling Large Datasets
Chapter 9: Parsing Specific Data Types
About the Author
Jacob Perkins is the cofounder and CTO of Weotta, a local search company. Weotta uses NLP and machine learning to create powerful and easy-to-use natural language search for what to do and where to go. He is the author of Python Text Processing with NLTK 2.0 Cookbook, Packt Publishing, and has contributed a chapter to the Bad Data Handbook, O’Reilly Media. He writes about NLTK, Python, and other technology topics at http: //streamhacker.com. To demonstrate the capabilities of NLTK and natural language processing, he developed http: //text-processing.com, which provides simple demos and NLP APIs for commercial use. He has contributed to various open source projects, including NLTK, and created NLTK-Trainer to simplify the process of training NLTK models. For more information, visit https: //github.com/japerk/nltk-trainer.

نقد و بررسیها
هنوز بررسیای ثبت نشده است.