

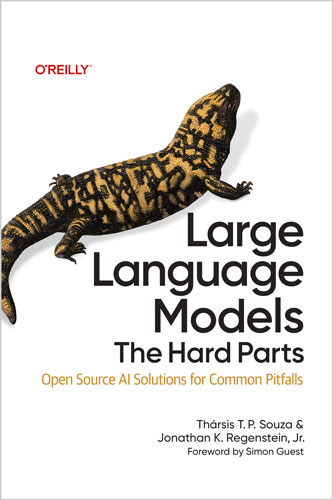
Large Language Models: The Hard Parts
Open Source AI Solutions for Common PitfallsThársis T. P. Souza and Jonathan K. Regenstein, Jr.
- ناشرO'Reilly
- سال انتشار2026
- ویرایش1
- زبانEnglish
- تعداد صفحات341
- شابک9798341622524
847,000 تومان – 2,040,000 تومانمحدوده قیمت: 847,000 تومان تا 2,040,000 تومان
تحویل اکسپرس
حمل رایگان سفارشات بالای 1 میلیون تومان
پرداخت امن
امکان پرداخت انلاین یا پرداخت حضروی درب منزل
ضمانت اصالت کالا
امکان پرداخت انلاین یا پرداخت حضروی درب منزل
7 روز گارانتی بازگشت وجه
امکان پرداخت انلاین یا پرداخت حضروی درب منزل
🧠 مدلهای زبانی بزرگ و چالشهای واقعی دنیای Production
🚀 مدلهای زبانی بزرگ یا همون LLMها تحول بزرگی توی دنیای پردازش زبان طبیعی ایجاد کردن، ولی وقتی پای استفادهی واقعی از این مدلها داخل اپلیکیشنها و سیستمهای Production وسط میاد، تازه چالشهای فنی جدی خودشون رو نشون میدن. کتاب Large Language Models: The Hard Parts دقیقاً روی همین بخش تمرکز کرده؛ یعنی محدودیتها، دردسرها و مشکلاتی که برنامهنویسها و مهندسهای AI موقع ساخت اپلیکیشنهای مبتنی بر LLM باهاش روبهرو میشن.
⚙️ این کتاب بهجای تمرکز روی قابلیتهای هیجانانگیز LLMها، سراغ مشکلات واقعی Implementation میره و با مثالهای قابل تکرار در پایتون و ابزارهای Open Source، راهکارهای عملی ارائه میکنه.
🎯 توی این کتاب یاد میگیری چطور با چالشهایی مثل ارزیابی مدلها، مدیریت Context، تستپذیری، ایمنی، خروجیهای غیرقابلاعتماد و Alignment کنار بیای و برای هرکدوم راهحل مهندسیشده داشته باشی.
🧪 استراتژیهای تست و Evaluation برای سیستمهای Non-Deterministic طراحی کن.
📚 مدیریت Context، معماریهای RAG و Retrieval در Contextهای طولانی رو یاد بگیر.
🧱 با مشکل ناپایداری خروجی و ساختارهای غیرقابلاعتماد مقابله کن.
🛡️ Frameworkهای ایمنی، Safety و Content Moderation پیادهسازی کن.
⚖️ چالشهای Alignment رو بررسی کن و تکنیکهای کاهش ریسک رو یاد بگیر.
💻 مدلهای Open Source رو بهصورت Local اجرا و استفاده کن.
📘 فهرست مطالب
- اصول اولیه — قبل از شروع ساخت سیستمهای مبتنی بر LLM چه چیزهایی باید در نظر بگیریم
- شکاف Evaluation
- ابزارهای Evaluation برای اپلیکیشنهای مبتنی بر LLM
- از داده تا Context
- خروجی ساختاریافتهی دادهها
- ملاحظات Safety در LLMها
- ارزیابی LLMها از نظر ایمنی
- Alignment در LLMها — یک Case Study
- سخن پایانی — مهندسهای اپلیکیشنهای LLM در عصر کاهش هزینهها
📖 از مقدمهی کتاب
🧠 نویسندهها توضیح میدن که این کتاب رو نوشتن چون نسبت به قدرت و آیندهی LLMها خوشبین هستن، ولی همزمان واقعبینانه میدونن که Deploy کردن موفق، گسترده و قابلاعتماد این مدلها کار سادهای نیست.
🔍 تمرکز اصلی کتاب روی افزایش آگاهی نسبت به چالشهای کلیدی LLMها و استفاده از راهکارهای Open Source برای حل اونهاست. کل مباحث کتاب با مثالهای عملی و قابل بازتولید در پایتون همراه شده تا صرفاً تئوری نباشه.
🚀 در پایان کتاب، خواننده فقط کسی نیست که «با LLMها کار کرده»، بلکه تبدیل میشه به کسی که میتونه یک اپلیکیشن مبتنی بر LLM قابلاعتماد بسازه؛ سیستمی که سازمان واقعاً بهش وابسته باشه.
🛠️ مهارتهایی مثل Evaluation، Safety، Context Engineering، Alignment، Structured Outputs، RAG و Fine-Tuning دقیقاً همون چیزهایین که تفاوت بین «فقط تست کردن LLMها» و «ساختن یک محصول Production-Ready» رو مشخص میکنن.
👥 این کتاب مناسب چه کسانیه؟
👨💻 دانشمندهای داده و مهندسهای ML که قبلاً با Machine Learning سنتی کار کردن و الان باید LLMها رو وارد سیستمهای Production کنن.
📊 مدیران محصول و رهبرهای فنی که باید تصمیم بگیرن آیا استفاده از LLM منطقیه یا نه، و اگر هست، چطور باید پیادهسازی بشه.
🏥 متخصصها و پژوهشگرهای حوزههایی مثل مالی، سلامت، حقوق یا آموزش که میخوان از LLMها استفاده کنن ولی نیاز دارن خروجیها رو دقیق و علمی ارزیابی کنن.
📈 متخصصهای Analytics و Business Intelligence که دنبال استفاده از LLMها برای تحلیل داده، تولید گزارش و استخراج Insight هستن.
🤖 افرادی که داخل سازمان مسئول «بررسی کاربرد AI» شدن؛ حتی اگر بکگراند ML نداشته باشن. این کتاب کمک میکنه دید واقعیتری نسبت به محدودیتها، ریسکها و قابلیتهای LLMها داشته باشن و بتونن تصمیمهای فنی آگاهانهتری بگیرن.
👨🏫 درباره نویسندهها
🧠 «دکتر تارسيس تی. پی. سوزا» دانشمند علوم کامپیوتر و رهبر محصول در حوزهی AIه که روی توسعهی محصولات مبتنی بر هوش مصنوعی تخصص داره. اون در بعضی از بزرگترین Hedge Fundهای والاستریت و استارتاپهای تکنولوژی سیلیکونولی نقش رهبری داشته. همچنین خالق پروژهی podcastfy.ai و مدرس سابق برنامهی کارشناسی ارشد تحلیل دادههای کاربردی در دانشگاه کلمبیا بوده.
🎓 او دارای مدرک دکتری علوم کامپیوتر از University College London و همچنین مدرکهای M.Phil، M.Sc و B.Sc در حوزهی علوم کامپیوتر و مهندسی کامپیوتره.
📚 «جاناتان کی. رگنستاین جونیور» سالها در تقاطع داده، Machine Learning، تکنولوژی و مدیریت سرمایه فعالیت کرده. او پژوهشگر وابسته به آزمایشگاه Financial Services Innovation Lab در دانشگاه جورجیا تک و مشاور استارتاپهای اولیهی AIه.
🏛️ او مدرک B.A خود را از دانشگاه هاروارد و مدرک حقوق J.D را از دانشگاه NYU دریافت کرده و در شهر آتلانتا همراه خانواده و سگهاش زندگی میکنه.
Large language models (LLMs) have transformed natural language processing, but deploying them in applications introduces numerous technical challenges. Large Language Models: The Hard Parts offers a clear, practical examination of the limitations developers and AI engineers face when building LLM-based applications. With a focus on implementation pitfalls (not just capabilities), this book provides actionable strategies supported by reproducible Python code and open source tools.
Readers will learn how to navigate key obstacles in application evaluation, input management, testing, and safety. Designed for builders and technical product leads, this guide emphasizes practical solutions to real-world problems and promotes a grounded understanding of LLM constraints and trade-offs.
- Design testing and evaluation strategies for nondeterministic systems
- Manage context, RAG, and long-context retrieval
- Address output inconsistency and structural unreliability
- Implement safety and content moderation frameworks
- Explore alignment challenges and mitigation techniques
- Leverage open source models locally
Table of Contents
Chapter 1. First Principles. What to Consider Before We Start Building with LLMs
Chapter 2. The Evals Gap
Chapter 3. Evaluation Tools for LLM-Based Applications
Chapter 4. From Data to Context
Chapter 5. Structured Data Output
Chapter 6. LLM Safety Considerations
Chapter 7. Evaluating LLMs for Safety
Chapter 8. LLM Alignment. A Case Study
Chapter 9. Epilogue. LLMBAs in the Era of Falling Costs
From the Preface
We wrote this book because we’re optimistic about the power and possibilities of LLMs but realistic about how hard it is to deploy them successfully, widely, and reliably. This book focuses on bringing awareness to key LLM challenges and harnessing open source solutions to overcome them. It offers a critical perspective on implementation, backed by practical and reproducible Python examples. By the book’s end, readers will be armed with the open source tools they need to become more than users of LLMs, and those tools will put us in a position to thrive in a world that is changing rapidly and offering the chance to move and build very quickly. The skills in this book—evaluation, safety, context, alignment, structured outputs, retrieval augmented generation (RAG), fine-tuning—are what differentiate “I played with LLMs” from “I built a reliable LLM-based application that my organization depends on.”
Who Should Read This Book
We wrote this book for data scientists, software engineers, and professionals across many fields. We list here some of those who we think will benefit most, but in reality we think anyone who wants to work with LLMs should read this book. More specifically:
- Data scientists and machine learning (ML) engineers who’ve worked with traditional ML but are now tasked with integrating LLMs into production systems.
- Product managers and technical leaders who need to make informed decisions about whether, when, and how to use LLMs. You’re responsible for outcomes.
- Researchers and domain experts in fields like finance, health care, law, or education—those who see potential for LLMs in their domain but need to understand how to validate their outputs. You know your domain inside out but may be skeptical of the AI hype. This book shows you how to rigorously evaluate whether an LLM aligns with your expertise.
- Analytics and business intelligence professionals exploring how LLMs can augment data analysis, report generation, or insight discovery. You’re comfortable with data, but LLMs are a new paradigm.
- Anyone tasked with “figuring out how we use AI”—an ever-growing group. Whether you’re in operations, HR, marketing, legal, or elsewhere, organizations are asking people without ML backgrounds to explore LLM applications. This book won’t make you an expert at building LLMs, but it will make you literate enough around LLM challenges to evaluate vendors, assess risks, understand what’s possible versus what’s hype, and have informed conversations with technical teams about implementation.
About the Author
Dr. Thársis T. P. Souza is a computer scientist and product leader specializing in AI-driven products. He has held leadership roles at some of Wall Street’s largest hedge funds and in early-stage Silicon Valley technology startups. He is the creator of podcastfy.ai and a former lecturer in the Master of Science in Applied Analytics program at Columbia University. He holds a Ph.D. in computer science from University College London, as well as an M.Phil. and M.Sc. in computer science and a B.Sc. in computer engineering.
Jonathan K. Regenstein, Jr., has spent his career working at the intersection of data, machine learning, technology, and asset management. He is a research affiliate at Georgia Tech’s Financial Services Innovation Lab and an advisor to early-stage AI companies. He holds a B.A. from Harvard University and a J.D. from NYU School of Law. He lives in Atlanta, Georgia, with his wife, three daughters, and three dogs.
| ناشر | O’Reilly |
|---|---|
| ویرایش | 1 |
| زبان | English |
| سال انتشار | 2026 |
| شابک | 9798341622524 |
| تعداد صفحات | 341 |
| قطع | B5 |
| کیفیت | اورجینال انتشارات |
| نوع چاپ | رنگی, سیاه و سفید |
| نوع جلد | جلد سخت, شومیز, طلقی |
محصولات مشابه
نقد و بررسیها
هنوز بررسیای ثبت نشده است.