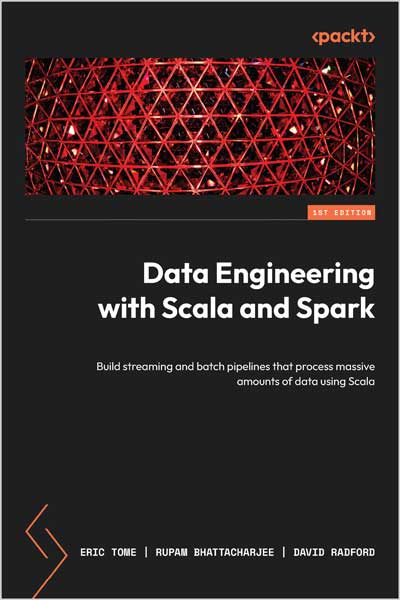
⚙️ این کتاب یک مسیر عملی و حرفهای برای ساخت Data Engineering Pipelineهای پیشرفته با استفاده از Scala + Apache Spark ارائه میده و تمرکزش روی عملکرد بالا، پردازش توزیعشده و طراحی سیستمهای production-ready هست.
🚀 هدف اصلی کتاب اینه که بتونی دادههای خام رو به یک منبع قابل اعتماد، تمیز و مقیاسپذیر برای سازمان تبدیل کنی؛ اون هم با استفاده از رویکردهای مهندسی نرمافزار مدرن مثل TDD و CI/CD.
🚀 در این کتاب یاد میگیری
🏗️ ساخت محیط توسعه برای توسعه Pipelineهای Scala
⚡ کار با Apache Spark شامل DataFrame، Dataset و Spark SQL
🔄 طراحی Pipelineهای batch و streaming
🧠 استفاده از مفاهیم پیشرفته Scala مثل polymorphic functions، type parameterization و implicits
📦 خواندن و نوشتن داده در Object Storage و Data Lakes
🔍 پروفایلینگ و تمیزسازی داده با Deequ
📊 بهینهسازی عملکرد Pipelineها در سطح سیستمهای توزیعشده
⚙️ پیادهسازی CI/CD با GitHub
🧪 استفاده از Test-Driven Development (TDD) برای افزایش کیفیت کد
🔁 ارکستریشن و مدیریت چرخه اجرای Pipelineها
📖 توضیحات کتاب
🧠 این کتاب Scala رو بهعنوان یک ابزار سطح بالا برای Data Engineering معرفی میکنه، مخصوصاً در سناریوهایی که performance و distributed computing اهمیت بالایی دارن.
⚡ برخلاف رویکردهای سادهتر مثل Python، اینجا تمرکز روی ساخت سیستمهایی هست که در مقیاس بزرگ، پایدار و قابل بهینهسازی باشن.
🏗️ از راهاندازی محیط توسعه تا طراحی Pipelineهای real-time، همه چیز مرحلهبهمرحله آموزش داده میشه.
⚙️ درباره فناوری
🔥 هسته اصلی کتاب بر پایه Apache Spark هست که یکی از مهمترین موتورهای پردازش داده در مقیاس بزرگ محسوب میشه.
🧩 Scala بهعنوان زبان اصلی استفاده میشه چون هم با Spark native هست و هم برای پردازش توزیعشده عملکرد بسیار بالایی داره.
☁️ همچنین مفاهیم cloud storage، data lake و orchestration هم در سطح production بررسی میشن.
📚 درباره کتاب
🧭 این کتاب فقط آموزش ابزار نیست؛ بلکه آموزش مهندسی سیستمهای دادهای واقعی هست.
💡 تمرکز روی اینه که چطور pipelineهایی بسازی که:
- قابل تست باشن
- قابل نگهداری باشن
- مقیاسپذیر باشن
- و در محیط production پایدار کار کنن
🔥 محتویات اصلی کتاب
⚙️ مفاهیم Scala برای Data Engineers
🛠️ راهاندازی محیط توسعه
⚡ کار با Apache Spark (DataFrame / Dataset / SQL)
📦 کار با Data Lake و Object Store
🔄 طراحی Data Transformation
🔍 Data Profiling و Data Quality
🧪 TDD و Code Maintainability
⚙️ CI/CD با GitHub
📡 Orchestration Pipeline
📊 Performance Tuning
🔁 Batch Pipeline Development
⚡ Streaming Pipeline Development
👥 این کتاب برای چه کسانی مناسبه؟
💻 برای Data Engineerهایی که تجربه دارن و میخوان وارد سطح پیشرفتهتر بشن، مخصوصاً در حوزه Spark، Scala و سیستمهای توزیعشده.
📑 فهرست مطالب
- مبانی Scala برای Data Engineers
- راهاندازی محیط توسعه
- معرفی Apache Spark و APIها
- کار با DataFrame / Dataset / Spark SQL
- کار با دیتابیسها
- Object Storage و Data Lake
- Data Transformation
- Data Profiling و Data Quality
- TDD و کیفیت کد
- CI/CD با GitHub
- Orchestration Pipeline
- Performance Tuning
- ساخت Batch Pipeline با Spark
- ساخت Streaming Pipeline با Spark
👨🏫 درباره نویسندگان
🧠 اریک تومه بیش از ۲۵ سال تجربه در حوزه داده داره و بهعنوان Senior Solutions Architect در Databricks روی طراحی سیستمهای داده و AI کار میکنه.
⚙️ روپام بهاتاچارجی Lead Data Engineer در IBM هست و تجربه زیادی در طراحی Pipelineهای بزرگ با Spark و Scala روی Hadoop و Cloud داره.
☁️ دیوید ردفورد یک متخصص Big Data و Cloud هست که روی مهاجرت سیستمهای legacy به معماریهای مدرن داده کار کرده و در حال حاضر در Databricks فعالیت میکنه.
Take your data engineering skills to the next level by learning how to utilize Scala and functional programming to create continuous and scheduled pipelines that ingest, transform, and aggregate data
Key Features
- Transform data into a clean and trusted source of information for your organization using Scala
- Build streaming and batch-processing pipelines with step-by-step explanations
- Implement and orchestrate your pipelines by following CI/CD best practices and test-driven development (TDD)
Book Description
Most data engineers know that performance issues in a distributed computing environment can easily lead to issues impacting the overall efficiency and effectiveness of data engineering tasks. While Python remains a popular choice for data engineering due to its ease of use, Scala shines in scenarios where the performance of distributed data processing is paramount.
This book will teach you how to leverage the Scala programming language on the Spark framework and use the latest cloud technologies to build continuous and triggered data pipelines. You’ll do this by setting up a data engineering environment for local development and scalable distributed cloud deployments using data engineering best practices, test-driven development, and CI/CD. You’ll also get to grips with DataFrame API, Dataset API, and Spark SQL API and its use. Data profiling and quality in Scala will also be covered, alongside techniques for orchestrating and performance tuning your end-to-end pipelines to deliver data to your end users.
By the end of this book, you will be able to build streaming and batch data pipelines using Scala while following software engineering best practices.
What you will learn
- Set up your development environment to build pipelines in Scala
- Get to grips with polymorphic functions, type parameterization, and Scala implicits
- Use Spark DataFrames, Datasets, and Spark SQL with Scala
- Read and write data to object stores
- Profile and clean your data using Deequ
- Performance tune your data pipelines using Scala
Who this book is for
This book is for data engineers who have experience in working with data and want to understand how to transform raw data into a clean, trusted, and valuable source of information for their organization using Scala and the latest cloud technologies.
Table of Contents
- Scala Essentials for Data Engineers
- Environment Setup
- An Introduction to Apache Spark and Its APIs – DataFrame, Dataset, and Spark SQL
- Working with Databases
- Object Stores and Data Lakes
- Understanding Data Transformation
- Data Profiling and Data Quality
- Test-Driven Development, Code Health, and Maintainability
- CI/CD with GitHub
- Data Pipeline Orchestration
- Performance Tuning
- Building Batch Pipelines Using Spark and Scala
- Building Streaming Pipelines Using Spark and Scala
About the Author
Eric Tome has over 25 years of experience working with data. He has contributed to and led teams that ingested, cleansed, standardized, and prepared data used by business intelligence, data science, and operations teams. He has a background in mathematics and currently works as a senior solutions architect at Databricks, helping customers solve their data and AI challenges.
Rupam Bhattacharjee works as a lead data engineer at IBM. He has architected and developed data pipelines, processing massive structured and unstructured data using Spark and Scala for on-premises Hadoop and K8s clusters on the public cloud. He has a degree in electrical engineering.
David Radford has worked in big data for over 10 years, with a focus on cloud technologies. He led consulting teams for several years, completing a migration from legacy systems to modern data stacks. He holds a master’s degree in computer science and works as a senior solutions architect at Databricks.

نقد و بررسیها
هنوز بررسیای ثبت نشده است.