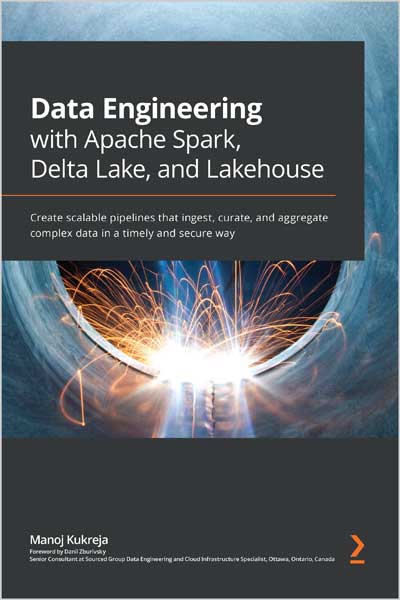
📘 درک پیچیدگیهای پلتفرمهای مدرن مهندسی داده
🧠 پیچیدگیهای پلتفرمهای مدرن Data Engineering رو درک کن و با کمک سناریوهای واقعی و تجربهی یک متخصص صنعت Big Data، استراتژیهای مقابله با اونها رو یاد بگیر.
⚙️ ویژگیهای کلیدی
🚀 با مفاهیم اصلی Apache Spark و Delta Lake آشنا میشی تا بتونی پلتفرمهای دادهی مقیاسپذیر بسازی.
📊 یاد میگیری چطور دادهها رو Ingest، پردازش و تحلیل کنی؛ دادههایی که بعداً برای آموزش مدلهای Machine Learning استفاده میشن.
🏭 همچنین درک میکنی چطور مدلهای داده رو در محیط Production عملیاتی کنی و با دادههای Curated به بهرهبرداری برسونی.
📖 توضیحات کتاب
🌪️ در دنیای دادههای همیشه در حال تغییر و Schemaهای پویا، ساخت Pipelineهایی که خودشون رو با تغییرات تطبیق بدن اهمیت زیادی داره. این کتاب بهت کمک میکنه پلتفرمهای دادهی مقیاسپذیر بسازی که مدیرها، Data Scientistها و Data Analystها بتونن بهش اعتماد کنن.
☁️ کتاب با معرفی مفاهیم پایه مهندسی داده و معماریهای اصلی شروع میشه و بعد وارد استفاده عملی از سرویسهای Microsoft Azure برای مهندسی داده میشه.
🧱 در ادامه با الگوهای طراحی Data Lake و مراحل مختلف جریان داده در یک Data Lake آشنا میشی. سپس قابلیتهای اصلی Delta Lake رو بررسی میکنی تا Data Lakeهایی با عملکرد بالا و Governance مناسب بسازی.
🏗️ بعد از اون، پیادهسازی معماری Lambda با استفاده از Delta Lake رو یاد میگیری. کتاب پر از مثالهای واقعی و سناریوهای Production هست که نویسنده در ۱۰ سال تجربه کار با Big Data باهاشون مواجه شده.
🚀 در نهایت هم استراتژیهای Deploy Data Lake رو یاد میگیری؛ از Provisioning منابع Cloud گرفته تا اجرای Pipelineها بهصورت تکرارپذیر و Continuous.
🧠 آنچه یاد میگیری
- شناخت چالشهای دنیای Data Engineering
- اضافه کردن تراکنشهای ACID به Apache Spark با Delta Lake
- طراحی Data Lakeهای Enterprise-Grade
- معماری Pipelineهای Ingestion کارآمد
- ارکستریشن Pipelineهای پیشپردازش با Spark و Delta Lake API
- اتوماسیون Deploy و مانیتورینگ Pipelineها در Production
- مدیریت امنیت، مانیتورینگ و کنترل Pipelineها
👥 مخاطب کتاب
🧑💻 این کتاب برای افرادیه که تازه وارد دنیای Data Engineering شدن یا Data Analystهایی که میخوان وارد مسیر ساخت پلتفرمهای مقیاسپذیر بشن.
⚡ همچنین برای کسانی مناسبه که با PySpark کار میکنن و میخوان Delta Lake رو وارد پروژههای خودشون کنن.
📌 پیشنیازها شامل آشنایی پایه با Python، Spark و SQL هست.
📚 فهرست مطالب
۱ داستان مهندسی داده و تحلیل
۲ آشنایی با معماریهای ذخیرهسازی و پردازش در Data Lake
۳ مهندسی داده در Microsoft Azure
۴ درک Pipelineهای داده
۵ مرحله جمعآوری داده – لایه برنز (Bronze Layer)
۶ آشنایی با Delta Lake
۷ مرحله پالایش داده – لایه نقرهای (Silver Layer)
۸ مرحله تجمیع داده – لایه طلایی (Gold Layer)
۹ استقرار و مانیتورینگ Pipelineها در Production
۱۰ حل چالشهای مهندسی داده
۱۱ آمادهسازی زیرساخت (Infrastructure Provisioning)
۱۲ CI/CD برای Pipelineهای داده
⭐ جمعبندی نقدها
🧩 این کتاب بهعنوان یک منبع قوی برای ورود به دنیای Delta Lake، Lakehouse، Databricks و Apache Spark شناخته میشه. همچنین معماری لایهای داده (Data Hops) رو خیلی شفاف توضیح میده.
🚀 برای افراد مبتدی تا سطح متوسط که میخوان سریع با روندهای جدید مهندسی داده آشنا بشن، گزینهی خیلی مناسبیه.
👨🏫 درباره نویسنده
🏗️ مانوج کوکریجا یک Principal Architect در Northbay Solutions هست که روی طراحی Data Lake و Pipelineهای داده در مقیاس بزرگ برای بانکها، شرکتهای بیمه و سازمانهای دولتی کار میکنه.
☁️ او سابقه کار در AWS، Azure، GCP و Alibaba Cloud داره و بیش از ۲۵ سال تجربه در حوزه IT و Big Data داره.
🎓 همچنین آخر هفتهها دورههای آموزشی برای مهندسهای داده و دانشجویان در حوزه Hadoop، Spark، Kafka و Cloud Analytics برگزار میکنه.
Understand the complexities of modern-day data engineering platforms and explore strategies to deal with them with the help of use case scenarios led by an industry expert in big data
Key Features
- Become well-versed with the core concepts of Apache Spark and Delta Lake for building data platforms
- Learn how to ingest, process, and analyze data that can be later used for training machine learning models
- Understand how to operationalize data models in production using curated data
Book Description
In the world of ever-changing data and schemas, it is important to build data pipelines that can auto-adjust to changes. This book will help you build scalable data platforms that managers, data scientists, and data analysts can rely on.
Starting with an introduction to data engineering, along with its key concepts and architectures, this book will show you how to use Microsoft Azure Cloud services effectively for data engineering. You’ll cover data lake design patterns and the different stages through which the data needs to flow in a typical data lake. Once you’ve explored the main features of Delta Lake to build data lakes with fast performance and governance in mind, you’ll advance to implementing the lambda architecture using Delta Lake. Packed with practical examples and code snippets, this book takes you through real-world examples based on production scenarios faced by the author in his 10 years of experience working with big data. Finally, you’ll cover data lake deployment strategies that play an important role in provisioning the cloud resources and deploying the data pipelines in a repeatable and continuous way.
By the end of this data engineering book, you’ll know how to effectively deal with ever-changing data and create scalable data pipelines to streamline data science, ML, and artificial intelligence (AI) tasks.
What you will learn
- Discover the challenges you may face in the data engineering world
- Add ACID transactions to Apache Spark using Delta Lake
- Understand effective design strategies to build enterprise-grade data lakes
- Explore architectural and design patterns for building efficient data ingestion pipelines
- Orchestrate a data pipeline for preprocessing data using Apache Spark and Delta Lake APIs
- Automate deployment and monitoring of data pipelines in production
- Get to grips with securing, monitoring, and managing data pipelines models efficiently
Who this book is for
This book is for aspiring data engineers and data analysts who are new to the world of data engineering and are looking for a practical guide to building scalable data platforms. If you already work with PySpark and want to use Delta Lake for data engineering, you’ll find this book useful. Basic knowledge of Python, Spark, and SQL is expected.
Table of Contents
- The Story of Data Engineering and Analytics
- Discovering Storage and Compute Data Lake Architectures
- Data Engineering on Microsoft Azure
- Understanding Data Pipelines
- Data Collection Stage – The Bronze Layer
- Understanding Delta Lake
- Data Curation Stage – The Silver Layer
- Data Aggregation Stage – The Gold Layer
- Deploying and Monitoring Pipelines in Production
- Solving Data Engineering Challenges
- Infrastructure Provisioning
- Continuous Integration and Deployment (CI/CD) of Data Pipelines
Review
“A great book to dive into data engineering! This book adds immense value for those who are interested in Delta Lake, Lakehouse, Databricks, and Apache Spark. It also explains different layers of data hops. I would recommend this book for beginners and intermediate-range developers who are looking to get up to speed with new data engineering trends with Apache Spark, Delta Lake, Lakehouse, and Azure. Worth buying!”
Ram Ghadiyaram, VP, JPMorgan Chase & Co.
“An excellent, must-have book in your arsenal if you’re preparing for a career as a data engineer or a data architect focusing on big data analytics, especially with a strong foundation in Delta Lake, Apache Spark, and Azure Databricks. Easy to follow with concepts clearly explained with examples, I am definitely advising folks to grab a copy of this book. Get practical skills from this book.”
Subhasish Ghosh, Cloud Solution Architect – Data & Analytics, Enterprise Commercial – US, Global Account – Customer Success Unit (CSU) team, Microsoft Corporation
About the Author
Manoj Kukreja is a Principal Architect at Northbay Solutions who specializes in creating complex Data Lakes and Data Analytics Pipelines for large-scale organizations such as banks, insurance companies, universities, and US/Canadian government agencies. Previously, he worked for Pythian, a large managed service provider where he was leading the MySQL and MongoDB DBA group and supporting large-scale data infrastructure for enterprises across the globe. With over 25 years of IT experience, he has delivered Data Lake solutions using all major cloud providers including AWS, Azure, GCP, and Alibaba Cloud. On weekends, he trains groups of aspiring Data Engineers and Data Scientists on Hadoop, Spark, Kafka and Data Analytics on AWS and Azure Cloud.


نقد و بررسیها
هنوز بررسیای ثبت نشده است.