سرعت بالا، سادگی، توانمندی در تحلیلهای پیشرفته و پشتیبانی چندزبانه، Apache Spark را به یک مهارت ضروری برای مهندسان داده و دانشمندان داده تبدیل کرده است. این راهنمای عملی، منبعی مناسب برای افرادی است که به دنبال آشنایی کاربردی با Spark هستند و میخواهند الگوریتمها و مثالهایی را با استفاده از PySpark بیاموزند.
در هر فصل از کتاب، نویسنده محمود پارسیان نحوه حل یک مسئله دادهای را با مجموعهای از تبدیلات Spark و الگوریتمها نشان میدهد. شما خواهید آموخت چگونه با مسائلی مانند ETL، الگوهای طراحی، الگوریتمهای یادگیری ماشین، پارتیشنبندی دادهها و تحلیل ژنوم روبهرو شوید. هر دستورالعمل شامل الگوریتمهای PySpark است که با اسکریپت درایور PySpark و شِل اجرا میشوند.
با مطالعه این کتاب میآموزید:
- چگونه تبدیلات مناسب Spark را برای رسیدن به راهحلهای بهینه انتخاب کنید
- با تبدیلات و کاهشدهندههای قدرتمند مانند
reduceByKey()، combineByKey() و mapPartitions() کار کنید
- نحوه پارتیشنبندی دادهها برای اجرای کوئریهای بهینه را درک کنید
- با استفاده از الگوهای طراحی PySpark، مدلهای تحلیلی ایجاد و اجرا کنید
- الگوریتمهای کشف موتیف را روی دادههای گرافی اعمال کنید
- با استفاده از API کتابخانه GraphFrames به تحلیل دادههای گرافی بپردازید
- الگوریتمهای PySpark را برای دادههای بالینی و ژنومی به کار بگیرید
- اصول ویژگیسازی (Feature Engineering) در الگوریتمهای یادگیری ماشین را درک و پیادهسازی کنید
- الگوهای طراحی دادهای کاربردی و عملگرا را بشناسید و بهکار ببرید
این کتاب یک راهنمای جامع برای پیادهسازی تحلیل دادهها در محیطهای توزیعشده با استفاده از PySpark است و برای کسانی که میخواهند در دنیای تحلیل دادههای بزرگ حرفهای شوند، ابزاری ارزشمند به حساب میآید.
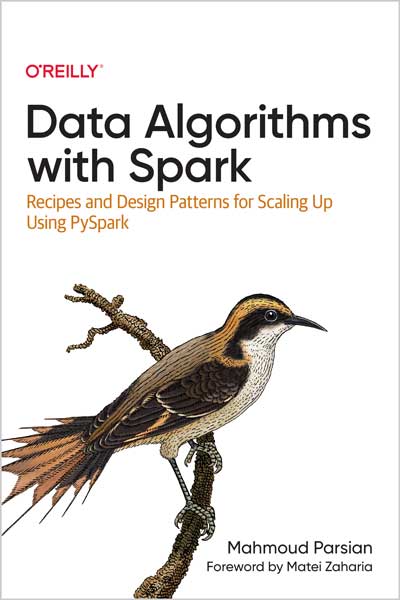
Apache Spark’s speed, ease of use, sophisticated analytics, and multilanguage support makes practical knowledge of this cluster-computing framework a required skill for data engineers and data scientists. With this hands-on guide, anyone looking for an introduction to Spark will learn practical algorithms and examples using PySpark.
In each chapter, author Mahmoud Parsian shows you how to solve a data problem with a set of Spark transformations and algorithms. You’ll learn how to tackle problems involving ETL, design patterns, machine learning algorithms, data partitioning, and genomics analysis. Each detailed recipe includes PySpark algorithms using the PySpark driver and shell script.
With this book, you will:
- Learn how to select Spark transformations for optimized solutions
- Explore powerful transformations and reductions including reduceByKey(), combineByKey(), and mapPartitions()
- Understand data partitioning for optimized queries
- Build and apply a model using PySpark design patterns
- Apply motif-finding algorithms to graph data
- Analyze graph data by using the GraphFrames API
- Apply PySpark algorithms to clinical and genomics data
- Learn how to use and apply feature engineering in ML algorithms
- Understand and use practical and pragmatic data design patterns
Table of Contents
Part I. Fundamentals
Chapter 1. Introduction to Spark and PySpark
Chapter 2. Transformations in Action
Chapter 3. Mapper Transformations
Chapter 4. Reductions in Spark
Part II. Working with Data
Chapter 5. Partitioning Data
Chapter 6. Graph Algorithms
Chapter 7. Interacting with External Data Sources
Chapter 8. Ranking Algorithms
Part III. Data Design Patterns
Chapter 9. Classic Data Design Patterns
Chapter 10. Practical Data Design Patterns
Chapter 11. Join Design Patterns
Chapter 12. Feature Engineering in PySpark
From the Preface
Spark has become the de facto standard for large-scale data analytics. I have been using and teaching Spark since its inception nine years ago, and I have seen tremendous improvements in Extract, Transform, Load (ETL) processes, distributed algorithm development, and large-scale data analytics. I started using Spark with Java, but I found that while the code is pretty stable, you have to write long lines of code, which can become unreadable. For this book, I decided to use PySpark (a Python API for Spark) because it is easier to express the power of Spark in Python: the code is short, readable, and maintainable. PySpark is powerful but simple to use, and you can express any ETL or distributed algorithm in it with a simple set of transformations and actions.
Why I Wrote This Book
This is an introductory book about data analysis using PySpark. The book consists of a set of guidelines and examples intended to help software and data engineers solve data problems in the simplest possible way. As you know, there are many ways to solve any data problem: PySpark enables us to write simple code for complex problems. This is the motto I have tried to express in this book: keep it simple and use parameters so that your solution can be reused by other developers. My aim is to teach readers how to think about data and understand its origins and final intended form, as well as showing how to use fundamental data transformation patterns to solve a variety of data problems.
Who This Book Is For
To use this book effectively it will be helpful to know the basics of the Python programming language, such as how to use conditionals (if-then-else), iterate through lists, and define and call functions. However, if your background is in another programming language (such as Java or Scala) and you do not know Python, you will still be able to use the book as I have provided a reasonable introduction to Spark and PySpark.
This book is primarily intended for people who want to analyze large amounts of data and develop distributed algorithms using the Spark engine and PySpark. I have provided simple examples showing how to perform ETL operations and write distributed algorithms in PySpark. The code examples are written in such a way that you can cut and paste them to get the job done easily.
About the Author
Mahmoud Parsian, Ph.D. in Computer Science, is a practicing software professional with 30 years of experience as a developer, designer, architect, and author. For the past 15 years, he has been involved in Java server-side, databases, MapReduce, Spark, PySpark, and distributed computing. Dr. Parsian currently leads Illumina’s Big Data team, which is focused on large-scale genome analytics and distributed computing by using Spark and PySpark. He leads and develops scalable regression algorithms; DNA sequencing pipelines using Java, MapReduce, PySpark, Spark, and open source tools. He is the author of the following books: Data Algorithms (O’Reilly, 2015), PySpark Algorithms (Amazon.com, 2019), JDBC Recipes (Apress, 2005), JDBC Metadata Recipes (Apress, 2006). Also, Dr. Parsian is an Adjunct Professor at Santa Clara University, teaching Big Data Modeling and Analytics and Machine Learning to MSIS program utilizing Spark, PySpark, Python, and scikit-learn.


نقد و بررسیها
هنوز بررسیای ثبت نشده است.