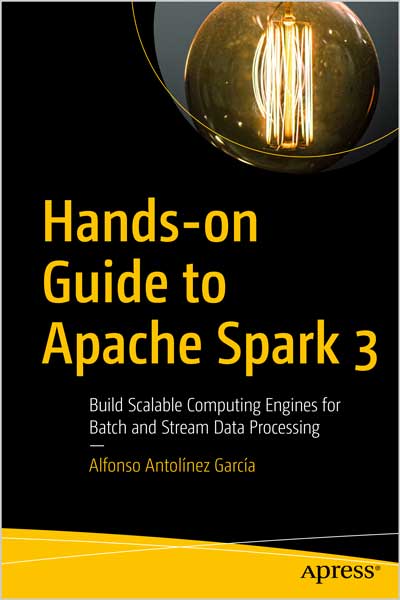
This book explains how to scale Apache Spark 3 to handle massive amounts of data, either via batch or streaming processing. It covers how to use Spark’s structured APIs to perform complex data transformations and analyses you can use to implement end-to-end analytics workflows.
This book covers Spark 3’s new features, theoretical foundations, and application architecture.
The first section introduces the Apache Spark ecosystem as a unified engine for large scale data analytics, and shows you how to run and fine-tune your first application in Spark. The second section centers on batch processing suited to end-of-cycle processing, and data ingestion through files and databases. It explains Spark DataFrame API as well as structured and unstructured data with Apache Spark. The last section deals with scalable, high-throughput, fault-tolerant streaming processing workloads to process real-time data. Here you’ll learn about Apache Spark Streaming’s execution model, the architecture of Spark Streaming, monitoring, reporting, and recovering Spark streaming.
A full chapter is devoted to future directions for Spark Streaming. With real-world use cases, code snippets, and notebooks hosted on GitHub, this book will give you an understanding of large-scale data analysis concepts–and help you put them to use.
Upon completing this book, you will have the knowledge and skills to seamlessly implement large-scale batch and streaming workloads to analyze real-time data streams with Apache Spark.
Table of Contents
Part I: Apache Spark Batch Data Processing
Chapter 1: Introduction to Apache Spark for Large-Scale Data Analytics
Chapter 2: Getting Started with Apache Spark
Chapter 3: Spark Low- Level API
Chapter 4: The Spark High-level APls
Chapter 5: Spark Dataset API and Adaptive Query Execution
Chapter 6: Introduction to Apache Spark Streaming
Part II: Apache Spark Streaming
Chapter 7: Spark Structured Streaming
Chapter 8: Streaming Sources and Sinks
Chapter 9: Event-Time Window Operations and Watermarking
Chapter 10: Future Directions for Spark Streaming
What You Will Learn
- Master the concepts of Spark clusters and batch data processing
- Understand data ingestion, transformation, and data storage
- Gain insight into essential stream processing concepts and different streaming architectures
- Implement streaming jobs and applications with Spark Streaming
Who This Book Is For
Data engineers, data analysts, machine learning engineers, Python and R programmers
About the Author
Alfonso Antolínez García is a senior IT manager with a long professional career serving in several multinational companies such as Bertelsmann SE, Lafarge, and TUI AG. He has been working in the media industry, the building materials industry, and the leisure industry. Alfonso also works as a university professor, teaching artificial intelligence, machine learning, and data science. In his spare time, he writes research papers on artificial intelligence, mathematics, physics, and the applications of information theory to other sciences.


نقد و بررسیها
هنوز بررسیای ثبت نشده است.