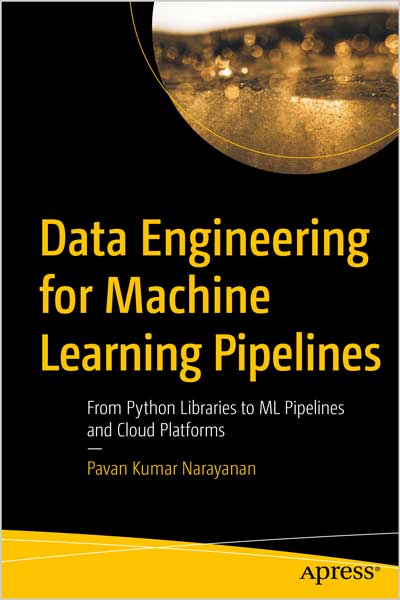
⚙️ این کتاب یک مسیر جامع و عملی برای یادگیری Data Engineering مدرن ارائه میده و تمرکزش روی استفاده از ابزارها و کتابخانههای Python برای ساخت Pipelineهای پیشرفته Machine Learning و سیستمهای دادهای یکپارچه هست.
🧠 هدف اصلی کتاب اینه که از سطح Data Wrangling تا طراحی سیستمهای Real-Time و Cloud-Based Data Pipelines رو به شکل مرحلهبهمرحله یاد بگیری.
🚀 در این کتاب یاد میگیری
🐼 کار با Pandas 2.0 برای تحلیل و تبدیل دادهها
⚡ استفاده از Polars (بر پایه Rust) و CuDF برای پردازش سریع روی CPU و GPU
🔍 طراحی Pipelineهای Data Validation با ابزارهایی مثل Pydantic، Pandera و Great Expectations
🌐 طراحی و توسعه APIهای داده با FastAPI شامل Authentication و Authorization
🧵 استفاده از Dask برای برنامهنویسی concurrent و ساخت Pipelineهای ML
📡 ساخت سیستمهای Real-Time با Apache Kafka
⚙️ ارکستریشن Workflow با Airflow و Prefect
☁️ پیادهسازی Pipelineها روی Cloudهای بزرگ مثل AWS، GCP و Azure
📖 توضیحات کتاب
📊 این کتاب ترکیبی از دانش نظری و پیادهسازی عملی هست و یک مسیر منظم از مفاهیم پایه تا تکنیکهای پیشرفته ارائه میده.
🚀 تمرکز اصلی روی ساخت سیستمهای دادهای مدرن هست که هم سریع باشن، هم مقیاسپذیر، هم قابل اعتماد.
🧩 در طول کتاب با پروژههای واقعی کار میکنی و یاد میگیری چطور از ابزارهای روز صنعت برای حل مسائل واقعی استفاده کنی.
⚙️ درباره فناوری
💡 این کتاب روی نسل جدید ابزارهای Data Engineering تمرکز داره؛ از کتابخانههای High-Performance مثل Polars و CuDF گرفته تا ابزارهای Cloud Native و Streaming.
📡 همچنین مفاهیم کلیدی مثل concurrency، orchestration و real-time processing در قالب پروژههای عملی آموزش داده میشن.
📚 درباره کتاب
🧠 کتاب Data Engineering with Modern Python Stack فقط آموزش ابزار نیست؛ بلکه یک مسیر حرفهای برای تبدیل شدن به Data Engineer سطح بالا هست.
🛠️ از تحلیل داده تا طراحی API، از validation تا deployment، همه مراحل یک چرخه واقعی مهندسی داده رو پوشش میده.
⚡ در نهایت یاد میگیری چطور pipelineهای ML و data systems رو در محیطهای واقعی پیادهسازی و deploy کنی.
🔥 محتویات اصلی کتاب
🐼 Data Wrangling با Pandas
⚡ پردازش سریع با Polars و CuDF
🔍 Data Validation و کیفیت داده
🌐 طراحی API با FastAPI
🧵 Concurrency با Dask
📡 Streaming با Kafka
⚙️ Workflow Orchestration با Airflow و Prefect
☁️ Deployment روی AWS، GCP و Azure
👥 این کتاب برای چه کسانی مناسبه؟
💻 برای Data Engineerها، Data Scientistها، ML Engineerها و MLOps Engineerهایی که میخوان مهارتهای عملی و صنعتی خودشون رو ارتقا بدن.
📑 فهرست مطالب
- مفاهیم پایه در Data Engineering
- Data Wrangling با Pandas
- Polars برای پردازش سریع
- CuDF و GPU-based Processing
- Data Validation با Pydantic و Pandera
- Data Validation با Great Expectations
- برنامهنویسی Concurrent با Dask
- ساخت ML Pipeline با DaskML
- ساخت Real-Time Pipeline با Kafka
- طراحی API داده با FastAPI
- مدیریت Workflowها
- Orchestration با Airflow
- Orchestration با Prefect
- Cloud Computing و Big Data
- AWS Pipelines
- GCP Pipelines
- Azure Pipelines
👨🏫 درباره نویسنده
🧠 پوان کومار نارایانان یک متخصص باتجربه در حوزه Data Engineering و Machine Learning هست که روی پروژههای پیچیده و مقیاسپذیر در صنعت IT کار کرده.
🏗️ تجربه او شامل سیستمهای Data Warehousing سنتی و همچنین معماریهای مدرن مبتنی بر API و سیستمهای پیامرسان هست.
☁️ او در حال حاضر در شرکت Ether Infinitum LLC فعالیت میکنه و روی توسعه Data Products و راهکارهای پیشرفته داده تمرکز داره.
This book covers modern data engineering functions and important Python libraries, to help you develop state-of-the-art ML pipelines and integration code.
The book begins by explaining data analytics and transformation, delving into the Pandas library, its capabilities, and nuances. It then explores emerging libraries such as Polars and CuDF, providing insights into GPU-based computing and cutting-edge data manipulation techniques. The text discusses the importance of data validation in engineering processes, introducing tools such as Great Expectations and Pandera to ensure data quality and reliability. The book delves into API design and development, with a specific focus on leveraging the power of FastAPI. It covers authentication, authorization, and real-world applications, enabling you to construct efficient and secure APIs using FastAPI. Also explored is concurrency in data engineering, examining Dask’s capabilities from basic setup to crafting advanced machine learning pipelines. The book includes development and delivery of data engineering pipelines using leading cloud platforms such as AWS, Google Cloud, and Microsoft Azure. The concluding chapters concentrate on real-time and streaming data engineering pipelines, emphasizing Apache Kafka and workflow orchestration in data engineering. Workflow tools such as Airflow and Prefect are introduced to seamlessly manage and automate complex data workflows.
What sets this book apart is its blend of theoretical knowledge and practical application, a structured path from basic to advanced concepts, and insights into using state-of-the-art tools. With this book, you gain access to cutting-edge techniques and insights that are reshaping the industry. This book is not just an educational tool. It is a career catalyst, and an investment in your future as a data engineering expert, poised to meet the challenges of today’s data-driven world.
What You Will Learn
- Elevate your data wrangling jobs by utilizing the power of both CPU and GPU computing, and learn to process data using Pandas 2.0, Polars, and CuDF at unprecedented speeds
- Design data validation pipelines, construct efficient data service APIs, develop real-time streaming pipelines and master the art of workflow orchestration to streamline your engineering projects
- Leverage concurrent programming to develop machine learning pipelines and get hands-on experience in development and deployment of machine learning pipelines across AWS, GCP, and Azure
Who This Book Is For
Data analysts, data engineers, data scientists, machine learning engineers, and MLOps specialists
Table of Contents
Chapter 1: Core Technologies in Data Engineering
Chapter 2: Data Wrangling using Pandas
Chapter 3: Data Wrangling using Rust’s Polars
Chapter 4: GPU Driven Data Wrangling Using CuDF
Chapter 5: Getting Started with Data Validation using Pydantic and Pandera
Chapter 6: Data Validation using Great Expectations
Chapter 7: Introduction to Concurrency Programming and Dask
Chapter 8: Engineering Machine Learning Pipelines using DaskML
Chapter 9: Engineering Real-time Data Pipelines using Apache Kafka
Chapter 10: Engineering Machine Learning and Data REST APIs using FastAPI
Chapter 11: Getting Started with Workflow Management and Orchestration
Chapter 12: Orchestrating Data Engineering Pipelines using Apache Airflow
Chapter 13: Orchestrating Data Engineering Pipelines using Prefect
Chapter 14: Getting Started with Big Data and Cloud Computing
Chapter 15: Engineering Data Pipelines Using Amazon Web Services
Chapter 16: Engineering Data Pipelines Using Google Cloud Platform
Chapter 17: Engineering Data Pipelines Using Microsoft Azure
About the Author
Pavan Kumar Narayanan has an extensive and diverse career in the information technology industry, with a primary focus on the data engineering and machine learning domains. Throughout his professional journey, he has consistently delivered solutions in environments characterized by heterogeneity and complexity. His experience spans a broad spectrum, encompassing traditional data warehousing projects following waterfall methodologies and extending to contemporary integrations that involve APIs and message-based systems. Pavan has made substantial contributions to large-scale data integrations for applications in data science and machine learning. At the forefront of these endeavors, he has played a key role in delivering sophisticated data products and solutions, employing a versatile mix of both traditional and agile approaches. Currently employed with Ether Infinitum LLC, Sheridan, WY, Pavan Kumar Narayanan continues to bring his wealth of experience to the forefront of the data engineering and machine learning landscape.

نقد و بررسیها
هنوز بررسیای ثبت نشده است.