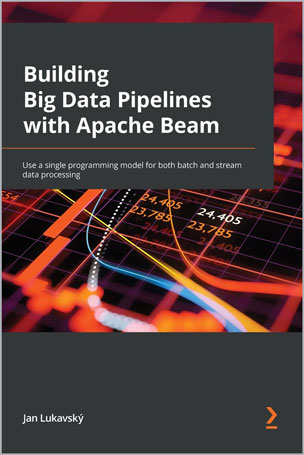
Implement, run, operate, and test data processing pipelines using Apache Beam
Key Features
- Understand how to improve usability and productivity when implementing Beam pipelines
- Learn how to use stateful processing to implement complex use cases using Apache Beam
- Implement, test, and run Apache Beam pipelines with the help of expert tips and techniques
Book Description
Apache Beam is an open source unified programming model for implementing and executing data processing pipelines, including Extract, Transform, and Load (ETL), batch, and stream processing.
This book will help you to confidently build data processing pipelines with Apache Beam. You’ll start with an overview of Apache Beam and understand how to use it to implement basic pipelines. You’ll also learn how to test and run the pipelines efficiently. As you progress, you’ll explore how to structure your code for reusability and also use various Domain Specific Languages (DSLs). Later chapters will show you how to use schemas and query your data using (streaming) SQL. Finally, you’ll understand advanced Apache Beam concepts, such as implementing your own I/O connectors.
By the end of this book, you’ll have gained a deep understanding of the Apache Beam model and be able to apply it to solve problems.
What you will learn
- Understand the core concepts and architecture of Apache Beam
- Implement stateless and stateful data processing pipelines
- Use state and timers for processing real-time event processing
- Structure your code for reusability
- Use streaming SQL to process real-time data for increasing productivity and data accessibility
- Run a pipeline using a portable runner and implement data processing using the Apache Beam Python SDK
- Implement Apache Beam I/O connectors using the Splittable DoFn API
Who this book is for
This book is for data engineers, data scientists, and data analysts who want to learn how Apache Beam works. Intermediate-level knowledge of the Java programming language is assumed.
Table of Contents
- Introduction to Data Processing with Apache Beam
- Implementing, Testing, and Deploying Basic Pipelines
- Implementing Pipelines Using Stateful Processing
- Structuring Code for Reusability
- Using SQL for Pipeline Implementation
- Using Your Preferred Language with Portability
- Extending Apache Beam’s I/O Connectors
- Understanding How Runners Execute Pipelines
About the Author
Jan Lukavský is a freelance big data architect and engineer who is also a committer of Apache Beam. He is a certified Apache Hadoop professional. He is working on open source big data systems combining batch and streaming data pipelines in a unified model, enabling the rise of real-time, data-driven applications.


نقد و بررسیها
هنوز بررسیای ثبت نشده است.