این کتاب دقیقاً همون چیزیه که برای درک عمیق پشتصحنه مدلهای تولید تصویر نیاز داری. قراره از صفر و مرحلهبهمرحله یاد بگیری چطور مدلهایی بسازی که متن رو میگیرن و تصویر تحویل میدن.
🤖 توی این مسیر با دو تا غول دنیای هوش مصنوعی یعنی Vision Transformers و Diffusion Models دستوپنج نرم میکنی و یاد میگیری چطور این مدلها رو شخصیسازی کنی یا توی پروژههای مولتیمدال ازشون استفاده کنی.
📑 فهرست مطالب
- داستان دو مدل: ترنسفورمرها و دیفیوژنها
- ساخت یک ترنسفورمر
- طبقهبندی تصاویر با استفاده از Vision Transformer
- اضافه کردن کپشن به تصاویر
- تولید تصویر با مدلهای دیفیوژن
- کنترل فرآیند تولید تصویر در مدلهای دیفیوژن
- تولید تصاویر با رزولوشن بالا در مدلهای دیفیوژن
- مدل CLIP: معیاری برای سنجش شباهت تصویر و متن
- تولید متن به تصویر با استفاده از Latent Diffusion
- عمیق شدن در مدل Stable Diffusion
- مدل VQGAN: تبدیل تصاویر به دنبالهای از اعداد صحیح
- پیادهسازی حداقلی مدل DALL-E
- چالشها و پیشرفتهای جدید در حوزه تولید متن به تصویر ضمیمه الف: نصب PyTorch و فعالسازی آموزش روی GPU به صورت محلی و در Colab
🌟 ویژگیهای کلیدی
• ساخت و آموزش مدلهایی برای تولید تصاویر با کیفیت بالا بر اساس توضیحات متنی
• ویرایش تصاویر موجود فقط با استفاده از Promptهای متنی
• طراحی و آموزش مدلی برای کپشننویسی خودکار روی عکسها
• ساخت یک Vision Transformer برای دستهبندی و کلاسبندی تصاویر
• فاینتیون کردن مدلهای زبانی بزرگ (LLM) برای کارهایی مثل تولید متن و تصویر
• تشخیص بهتر تصاویر واقعی از فیک (Deepfakes)
🚀 آنچه یاد خواهید گرفت
• درک عمیق معماری ترنسفورمرها و نحوه عملکرد فرآیند Denoising در دیفیوژن
• کار با کتابخانههای پایتونی و PyTorch برای پیادهسازی مدلهای سنگین
• نحوه تبدیل تصاویر به توکن (Patch Tokenization) و بازسازی مجدد آنها
• تسلط بر مدلهایی مثل Stable Diffusion و DALL-E از نمای نزدیک
👨💻 درباره نویسنده
دکتر مارک لیو، استاد دانشگاه کنتاکی و متخصص حوزه مالیه که بیش از 20 سال سابقه کدنویسی حرفهای داره و پیچیدهترین مفاهیم هوش مصنوعی رو به زبان ساده و کاربردی توضیح میده.
این کتاب برای کسانی که پایتون بلدن و میخوان از لایه “کاربر ساده” فراتر برن و بفهمن زیر کاپوت این مدلهای خفن چی میگذره، عالیه.
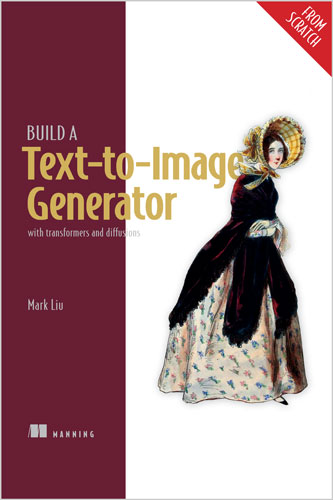
This book takes you step-by-step through creating your own AI models that can generate images from text. You’ll explore two methods of image generation—vision transformers and diffusion models—and learn vital AI development techniques as you go.
Dive into the powerful models behind AI image generators. The best way to learn is to build something from scratch, and in this book you’ll build your very own diffusion model and vision transformer. As you work through each stage of development, you’ll develop an understanding of how these models can be customized, applied, and integrated for impressive multimodal AI.
Build a Text-to-Image Generator (from Scratch) teaches you how to:
• Build and train models to generate high resolution images based on text descriptions
• Edit an existing image based on text prompts
• Build and train a model to add captions to images
• Build and train a vision transformer to classify images
• Fine-tune LLMs for downstream tasks such as classification, text or image generation
• Better differentiate real images from deepfakes
About the technology
AI-generated images appear everywhere from high-end advertising to casual social media feeds. Text-to-image tools like Dall-e, Midjourney, and Flux make it easy to create AI art, but how do they work? In this book, you’ll find out by building your own text-to-image generator!
About the book
Build a Text-to-Image Generator (from Scratch) explores both transformer-based image generation and diffusion models. You’ll work hands-on to build a pair of simple generation models that can classify images, automatically add captions, reconstruct images, and enhance existing graphics. Author Mark Liu guides you every step of the way with clear explanations, informative diagrams, and eye-opening examples you can build on your own laptop.
What’s inside
• Build a vision transformer to classify images
• Edit images using text prompts
• Fine-tune image models
About the reader
Requires basic knowledge of generative AI models and intermediate Python skills.
Table of Contents
Part 1. Understanding attention
1. A tale of two models: Transformers and diffusions
2. Build a transformer
3. Classify images with a vision transformer
4. Add captions to images
Part 2. Introduction to diffusion models
5. Generate images with diffusion models
6. Control what images to generate in diffusion models
7. Generate high-resolution images with diffusion models
Part 3. Text-to-image generation with diffusion models
8. CLIP: A model to measure the similarity between image and text
9. Text-to-image generation with latent diffusion
10. A deep dive into Stable Diffusion
Part 4. Text-to-image generation with transformers
11. VQGAN: Convert images into sequences of integers
12. A minimal implementation of DALL-E
Part 5. New developments and challenges
13. New developments and challenges in text-to-image generation
Appendix A Installing PyTorch and enabling GPU training locally and in Colab
why this book?
Build a Text-to-Image Generator (from Scratch) guides you step-by-step through building your own text-to-image generator – using both transformer-based and diffusion-based approaches – so you learn how modern image-generation systems (like Stable Diffusion or DALL·E) actually work under the hood.
Through practical, runnable examples (in Python/PyTorch), it helps you gain hands-on experience: you’ll build models that can generate images from text prompts, edit existing images based on prompts, caption images, classify images, or even detect deepfakes.
By the end, you’ll not only understand the theory — how vision transformers, patch tokenization, diffusion, and denoising work — but also have the skills to customize, fine-tune, and deploy your own multimodal AI models tailored to your data or creative needs.
About the Author
Dr. Mark Liu is a tenured finance professor and the founding director of the Master of Science in Finance program at the University of Kentucky. He has more than 20 years of coding experience, a Ph.D. in finance from Boston College.

نقد و بررسیها
هنوز بررسیای ثبت نشده است.