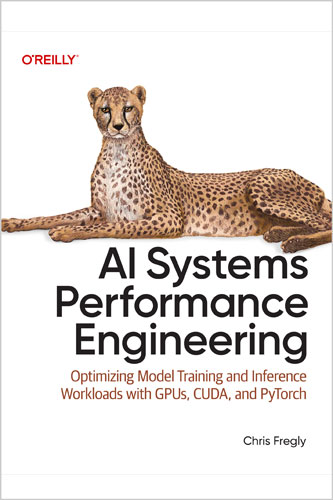
⚡ بهینهسازی عملکرد سیستمهای هوش مصنوعی: راهنمای جامع
با این کتاب مهارتهای لازم برای افزایش کارایی هر لایه از زیرساخت AI را یاد بگیر و سیستمهایی مقیاسپذیر، مقاوم و کمهزینه بساز که هم در آموزش و هم در استنتاج عالی عمل کنند.
✨ ویژگیهای کلیدی
• طراحی و بهینهسازی همزمان سختافزار، نرمافزار و الگوریتمها برای حداکثر بازده و صرفهجویی در هزینه
• پیادهسازی استراتژیهای استنتاج پیشرفته برای کاهش تأخیر و افزایش throughput در محیطهای واقعی
• استفاده از ابزارها و فریمورکهای پیشرفته مقیاسپذیری
• پروفایلگیری، تشخیص و رفع گلوگاههای عملکردی در خطوط پردازشی پیچیده AI
• ادغام تکنیکهای بهینهسازی full-stack برای عملکرد پایدار و قابل اعتماد سیستمهای AI
📘 توضیح کتاب
در دنیای امروز که مدلهای زاینده روز به روز بزرگتر میشوند، AI Systems Performance Engineering مهندسان، پژوهشگران و توسعهدهندگان را با مجموعهای از استراتژیهای بهینهسازی عملی مجهز میکند. در این کتاب، روشهای گامبهگام برای بهینهسازی GPU CUDA kernels، الگوریتمهای مبتنی بر PyTorch و سیستمهای آموزش و استنتاج چندنودی آموزش داده میشود. همچنین هنر مقیاسدهی GPU clusters، jobهای آموزش توزیعشده و inference servers را یاد میگیری. کتاب با یک چکلیست بیش از ۱۷۵ موردی از بهینهسازیهای اثباتشده و آماده استفاده پایان مییابد.
🎯 آنچه یاد خواهید گرفت
• بهینهسازی سختافزار، نرمافزار و الگوریتمها برای حداکثر throughput و صرفهجویی در هزینه
• کاهش تأخیر و افزایش کارایی inference با استراتژیهای پیشرفته
• استفاده از ابزارها و فریمورکهای مقیاسپذیری پیشرو
• تشخیص و رفع گلوگاهها در خطوط پردازشی AI
• یکپارچهسازی تکنیکهای full-stack برای عملکرد قابل اعتماد و مقاوم
📑 فهرست مطالب
- معرفی و مروری بر سیستم AI
- مروری بر سختافزار سیستم AI
- بهینهسازی OS، Docker و Kubernetes برای محیطهای GPU
- بهینهسازی ارتباطات شبکه توزیعشده
- بهینهسازی I/O ذخیرهسازی مبتنی بر GPU
- معماری GPU، برنامهنویسی CUDA و افزایش Occupancy
- پروفایلگیری و بهینهسازی الگوهای دسترسی حافظه GPU
- تنظیم Occupancy، کارایی Warp و موازیسازی سطح دستور
- افزایش کارایی CUDA Kernel و شدت محاسباتی
- Intra-Kernel Pipelining، تخصص Warp و Cooperative Thread Block Clusters
- Inter-Kernel Pipelining، هماهنگی و تخصیص حافظه به ترتیب CUDA Stream
- برنامهریزی دینامیک، CUDA Graphs و ارکستریشن Kernel توسط دستگاه
- پروفایلگیری، بهینهسازی و مقیاسدهی PyTorch
- PyTorch Compiler، OpenAI Triton و XLA Backends
- استنتاج چندنودی، موازیسازی، Decoding و بهینهسازی Routing
- پروفایلگیری، دیباگ و بهینهسازی استنتاج در مقیاس بزرگ
- مقیاسدهی Prefill و Decode تفکیکشده برای استنتاج
- بهینهسازی پیشرفته Prefill-Decode و KV Cache
- بهینهسازی موتور استنتاج دینامیک و تطبیقی
- بهینهسازی عملکرد با کمک AI و مقیاسدهی به GPU Clusterهای چندمیلیونی
👤 درباره نویسنده
کریس فرگلی یک مهندس عملکرد و رهبر محصول AI است که نوآوریهایی را در Netflix، Databricks، Amazon Web Services (AWS) و چندین استارتاپ هدایت کرده. او تیمهای مهندسی متمرکز بر عملکرد را رهبری کرده که محصولات AI/ML را ساخته، پروژههای بازار را مقیاسدهی کرده و هزینهها را برای workloadهای بزرگ generative-AI کاهش دادهاند. کریس نویسنده مشترک کتابهای O’Reilly Data Science on AWS و Generative AI on AWS و خالق دوره O’Reilly High-Performance AI in Production with NVIDIA GPUs است. فعالیتهای او شامل tuning سطح kernel، شتابدهی مبتنی بر کامپایلر، آموزش توزیعشده و inference با throughput بالا است. او همچنین سازماندهنده meetup جهانی AI Performance Engineering با بیش از ۱۰۰,۰۰۰ عضو در سراسر جهان است.
Elevate your AI system performance capabilities with this definitive guide to maximizing efficiency across every layer of your AI infrastructure. In today’s era of ever-growing generative models, AI Systems Performance Engineering provides engineers, researchers, and developers with a hands-on set of actionable optimization strategies. Learn to co-optimize hardware, software, and algorithms to build resilient, scalable, and cost-effective AI systems that excel in both training and inference. Authored by Chris Fregly, a performance-focused engineering and product leader, this resource transforms complex AI systems into streamlined, high-impact AI solutions.
Inside, you’ll discover step-by-step methodologies for fine-tuning GPU CUDA kernels, PyTorch-based algorithms, and multinode training and inference systems. You’ll also master the art of scaling GPU clusters for high performance, distributed model training jobs, and inference servers. The book ends with a 175+-item checklist of proven, ready-to-use optimizations.
- Codesign and optimize hardware, software, and algorithms to achieve maximum throughput and cost savings
- Implement cutting-edge inference strategies that reduce latency and boost throughput in real-world settings
- Utilize industry-leading scalability tools and frameworks
- Profile, diagnose, and eliminate performance bottlenecks across complex AI pipelines
- Integrate full stack optimization techniques for robust, reliable AI system performance
Table of Contents
Chapter 1. Introduction and AI System Overview
Chapter 2. AI System Hardware Overview
Chapter 3. OS, Docker, and Kubernetes Tuning for GPU-Based Environments
Chapter 4. Tuning Distributed Networking Communication
Chapter 5. GPU-Based Storage I/O Optimizations
Chapter 6. GPU Architecture, CUDA Programming, and Maximizing Occupancy
Chapter 7. Profiling and Tuning GPU Memory Access Patterns
Chapter 8. Occupancy Tuning, Warp Efficiency, and Instruction-Level Parallelism
Chapter 9. Increasing CUDA Kernel Efficiency and Arithmetic Intensity
Chapter 10. Intra-Kernel Pipelining, Warp Specialization, and Cooperative Thread Block Clusters
Chapter 11. Inter-Kernel Pipelining, Synchronization, and CUDA Stream-Ordered Memory Allocations
Chapter 12. Dynamic Scheduling, CUDA Graphs, and Device-Initiated Kernel Orchestration
Chapter 13. Profiling, Tuning, and Scaling PyTorch
Chapter 14. PyTorch Compiler, OpenAI Triton, and XLA Backends
Chapter 15. Multinode Inference, Parallelism, Decoding, and Routing Optimizations
Chapter 16. Profiling, Debugging, and Tuning Inference at Scale
Chapter 17. Scaling Disaggregated Prefill and Decode for Inference
Chapter 18. Advanced Prefill-Decode and KV Cache Tuning
Chapter 19. Dynamic and Adaptive Inference Engine Optimizations
Chapter 20. AI-Assisted Performance Optimizations and Scaling Toward Multimillion GPU Clusters
Review
“AI systems are layered and fast-moving. Chris breaks the complexity down into a reference that will set the standard for years.”
–Chris Lattner, CEO at Modular
“CUDA kernels, distributed training, compilers, disaggregated inference—finally in one place. An encyclopedia of ML systems.”
–Mark Saroufim, PyTorch at Meta (and Founder of GPU MODE Community)
“Squeezing the most performance out of your AI system is what separates the good from the great. This is the missing manual.”
—Sebastian Raschka, ML/AI Researcher
“An essential guide to modern ML systems—grounded in vLLM and distributed systems—with deep insight into inference optimization and open source.”
—Michael Goin, vLLM Maintainer and Principal Engineer at Red Hat
“A definitive field guide that connects silicon to application, giving AI engineers the full‑stack wisdom to turn raw compute into high‑performance models.”
—Harsh Banwait, Director of Product at Coreweave
About the Author
Chris Fregly is a performance engineer and AI product leader who has driven innovations at Netflix, Databricks, Amazon Web Services (AWS), and multiple startups. He has led performance-focused engineering teams that built AI/ML products, scaled go-to-market initiatives, and reduced cost for large-scale generative-AI and analytics workloads. Chris is coauthor of the OâReilly books Data Science on AWS and Generative AI on AWS, and creator of the OâReilly course “High-Performance AI in Production with NVIDIA GPUs.” His work spans kernel-level tuning, compiler-driven acceleration, distributed training, and high-throughput inference. Chris is the organizer of the global AI Performance Engineering meetup with over 100,000 members worldwide.

نقد و بررسیها
هنوز بررسیای ثبت نشده است.