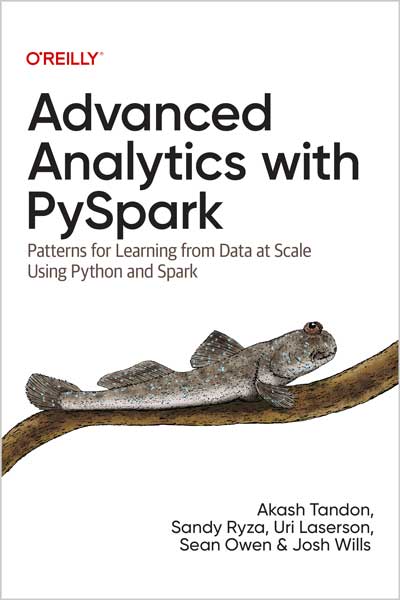
The amount of data being generated today is staggering and growing. Apache Spark has emerged as the de facto tool to analyze big data and is now a critical part of the data science toolbox. Updated for Spark 3.0, this practical guide brings together Spark, statistical methods, and real-world datasets to teach you how to approach analytics problems using PySpark, Spark’s Python API, and other best practices in Spark programming.
Data scientists Akash Tandon, Sandy Ryza, Uri Laserson, Sean Owen, and Josh Wills offer an introduction to the Spark ecosystem, then dive into patterns that apply common techniques-including classification, clustering, collaborative filtering, and anomaly detection, to fields such as genomics, security, and finance. This updated edition also covers NLP and image processing.
If you have a basic understanding of machine learning and statistics and you program in Python, this book will get you started with large-scale data analysis.
- Familiarize yourself with Spark’s programming model and ecosystem
- Learn general approaches in data science
- Examine complete implementations that analyze large public datasets
- Discover which machine learning tools make sense for particular problems
- Explore code that can be adapted to many uses
Table of Contents
1. Analyzing Big Data
2. Introduction to Data Analysis with PySpark
3. Recommending Music and the Audioscrobbler Dataset
4. Making Predictions with Decision Trees and Decision Forests
5. Anomaly Detection with K-means Clustering
6. Understanding Wikipedia with LDA and Spark NLP
7. Geospatial and Temporal Data Analysis on Taxi Trip Data
8. Estimating Financial Risk
9. Analyzing Genomics Data and the BDG Project
10. Image Similarity Detection with Deep Learning and PySpark LSH
11. Managing the Machine Learning Lifecycle with MLflow
About the Authors
Akash Tandon is an independent consultant and experienced full-stack data engineer. Previously, he was a senior data engineer at Atlan, where he built software for enterprise data science teams. In another life, he had worked on data science projects for governments, and built risk assessment tools at a FinTech startup. As a student, he wrote open source software with the R project for statistical computing and Google. In his free time, he researches things for no good reason.
Sandy Ryza is software engineer at Elementl. Previously, he developed algorithms for public transit at Remix and was a senior data scientist at Cloudera and Clover Health. He is an Apache Spark committer, Apache Hadoop PMC member, and founder of the Time Series for Spark project.
Uri Laserson is founder & CTO of Patch Biosciences. Previously, he worked on big data and genomics at Cloudera.
Sean Owen is a principal solutions architect focusing on machine learning and data science at Databricks. He is an Apache Spark committer and PMC member, and co-author Advanced Analytics with Spark. Previously, he was director of Data Science at Cloudera and an engineer at Google.
Josh Wills is an independent data science and engineering consultant, the former head of data engineering at Slack and data science at Cloudera, and wrote a tweet about data scientists once.


نقد و بررسیها
هنوز بررسیای ثبت نشده است.