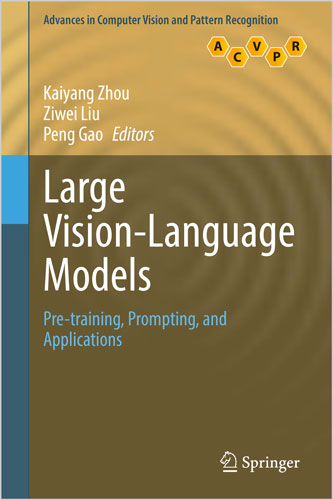
📘 پیشرفت سریع مدلهای پایه چندرسانهای بزرگ، به ویژه مدلهای بینایی-زبان بهطور چشمگیری چشمانداز یادگیری ماشین، بینایی کامپیوتری و پردازش زبان طبیعی را تغییر داده است. این مدلهای قدرتمند که با حجم عظیمی از دادههای چندرسانهای شامل تصاویر و متن آموزش دیدهاند، توانمندیهای قابلتوجهی در کارهایی مانند طبقهبندی تصاویر، شناسایی اشیاء، تولید محتوای بصری و پاسخ به پرسشها نشان دادهاند. این کتاب یک بررسی جامع و بهروز از مدلهای بزرگ بینایی-زبان (VLM) ارائه میدهد و جنبههای کلیدی پیشآموزش، تکنیکهای پرومپتینگ و کاربردهای متنوع در دنیای واقعی بینایی کامپیوتری را پوشش میدهد. این اثر منبعی ضروری برای پژوهشگران، متخصصان و دانشجویان بینایی کامپیوتری، پردازش زبان طبیعی و هوش مصنوعی است.
🔹 محتوای کتاب:
کتاب Large Vision-Language Models با بررسی اصول مدلهای بینایی-زبان آغاز میشود و طراحی معماری، تکنیکهای آموزش و روشهای ساخت دیتاستها را پوشش میدهد. سپس استراتژیهای پرومپتینگ و روشهای انطباق دیگر بررسی میشوند تا نشان دهند چگونه میتوان این مدلها را برای وظایف متنوع پاییندست (downstream tasks) بهینهسازی کرد. بخش نهایی کتاب به کاربردهای مدلهای بینایی-زبان در حوزههای مختلف مانند شناسایی اشیاء با دیکشنری باز، پردازش ابر نقاط سهبعدی و تولید و دستکاری محتوای بصری با متن میپردازد.
🌐 کاربردها و چالشها:
علاوه بر مبانی فنی، کتاب کاربردهای گسترده مدلهای بینایی-زبان را بررسی میکند؛ از بهبود سیستمهای شناسایی تصویر گرفته تا تولید محتوای بصری پیشرفته و تعامل طبیعیتر انسان-ماشین. همچنین چالشهای کلیدی مانند همترازی ویژگیها، مقیاسپذیری، نیازهای داده و معیارهای ارزیابی مورد بحث قرار میگیرند. این اثر، نقشه راه جامعی برای تازهواردان و کارشناسان ارائه میدهد و به درک چشمانداز فعلی، محدودیتها و مسیرهای آینده VLMها کمک میکند و در نهایت به پیشرفت هوش مصنوعی یاری میرساند.
👨💻 درباره نویسندگان:
Kaiyang Zhou
☑️ استادیار دانشگاه Baptist هنگکنگ در رشته علوم کامپیوتر، متخصص در بینایی کامپیوتری و یادگیری ماشین
☑️ بیش از ۳۰ مقاله در ژورنالها و کنفرانسهای سطح بالا منتشر کرده و بیش از ۱۰,۰۰۰ استناد دریافت کرده است
☑️ دبیر همکار IJCV و عضو کمیته علمی ارشد کنفرانسهای NeurIPS، CVPR، ECCV و AAAI
Ziwei Liu
☑️ دانشیار دانشگاه فناوری نانیانگ، سنگاپور، متخصص در بینایی کامپیوتری، یادگیری ماشین و گرافیک کامپیوتری
☑️ برنده جوایز متعدد مانند ICCV Young Researcher Award و MIT Technology Review Innovators under 35 Asia Pacific
☑️ سردبیر و عضو کمیته علمی کنفرانسهای CVPR، ICCV، ECCV، NeurIPS و ICLR
Peng Gao
☑️ دانشمند پژوهشی در Shanghai Artificial Intelligence Laboratory، متخصص در مدلهای زبان بزرگ و مدلهای بینایی-زبان
☑️ بیش از ۴۰ مقاله در ژورنالها و کنفرانسهای برتر منتشر کرده و بیش از ۱۰,۰۰۰ استناد دریافت کرده است
☑️ رهبر پروژههای منبع باز تأثیرگذار مانند LLaMa-Adapter و Lumina series با هزاران ستاره در GitHub
The rapid progress in the field of large multimodal foundation models, especially vision-language models, has dramatically transformed the landscape of machine learning, computer vision, and natural language processing. These powerful models, trained on vast amounts of multimodal data mixed with images and text, have demonstrated remarkable capabilities in tasks ranging from image classification and object detection to visual content generation and question answering. This book provides a comprehensive and up-to-date exploration of large vision-language models, covering the key aspects of their pre-training, prompting techniques, and diverse real-world computer vision applications. It is an essential resource for researchers, practitioners, and students in the fields of computer vision, natural language processing, and artificial intelligence.
Large Vision-Language Models begins by exploring the fundamentals of large vision-language models, covering architectural designs, training techniques, and dataset construction methods. It then examines prompting strategies and other adaptation methods, demonstrating how these models can be effectively fine-tuned to address a wide range of downstream tasks. The final section focuses on the application of vision-language models across various domains, including open-vocabulary object detection, 3D point cloud processing, and text-driven visual content generation and manipulation.
Beyond the technical foundations, the book explores the wide-ranging applications of vision-language models (VLMs), from enhancing image recognition systems to enabling sophisticated visual content generation and facilitating more natural human-machine interactions. It also addresses key challenges in the field, such as feature alignment, scalability, data requirements, and evaluation metrics. By providing a comprehensive roadmap for both newcomers and experts, this book serves as a valuable resource for understanding the current landscape, limitations, and future directions of VLMs, ultimately contributing to the advancement of artificial intelligence.
Table of Contents
1. Foundations of Vision-Language Models: Concepts and Roadmap
Part I. Scaling Intelligence: Pre-Training Strategies for Vision-Language Models
2. InternVL: Scaling up Vision Foundation Models and Aligning for Genetic Visual-Linguistic Tasks
3. Multimodal Large Language Models for Video Understanding
4. Generative Multimodal Models Are In-Context Learners
Part II. Shaping Intelligence: Prompting Techniques for Multimodal Adaptation
5. Differentiable Prompt Learning for Vision-Language Models
6. Test-Time Prompt Tuning for Vision-Language Models
7. Learning Efficient Feature Adapters for Vision-Language Models
8. Efficient Tuning of Vision Foundation Models with Neural Prompt Search
9. Confidence Calibration in Contrastive Vision-Language Models
Part III. Applying Intelligence: Real-World Applications of Vision-Language Models
10. Open-Vocabulary Object Detection Based on Detection Transformers
11. Unlocking CLIP for Zero-Shot Dense Segmentation
12. Adapting CLIP for 3D Understanding
13. Multimodal Face Generation and Manipulation with Collaborative Diffusion Models
14. Boosting Diffusion U-Net with Free Lunch for Text-to-Image and Text-to-Video Generation
15. Text-Conditioned Zero-Shot 3D Avatar Creation and Animation
16. Text-Driven 3D Human Motion Generation
17. Text-Driven Scene Generation
About the Author
Kaiyang Zhou is an Assistant Professor at the Department of Computer Science, Hong Kong Baptist University, working on computer vision and machine learning. He has published more than 30 technical papers in top-tier journals and conferences in relevant fields, including CVPR, ICCV, ECCV, NeurlPS, ICLR, ICML, AAAI, IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), and International Journal of Computer Vision (IJCV), with over 10,000 citations received in total. He is an Associate Editor of IJCV, the flagship journal in computer vision, and regularly serves as area chair and senior program committee for top-tier computer vision and machine learning conferences, such as NeurIPS, CVPR, ECCV, and AAAI.
Ziwei Liu is an Associate Professor at Nanyang Technological University, Singapore. His research interests include computer vision, machine learning, and computer graphics. He has published extensively with top-tier conferences and journals in relevant fields, including CVPR, ICCV, ECCV, NeurlPS, ICLR, ICML, IEEE Transactions on Pattern Analysis and Machine Intelligence, ACM Transactions on Graphics and Nature – Machine Intelligence. He is the recipient of ICCV Young Researcher Award, HKSTP Best Paper Award, CVPR Best Paper Award Candidate, ICBS Frontiers of Science Award and MIT Technology Review Innovators under 35 Asia Pacific. He serves as an area chair of CVPR, ICCV, ECCV, NeurlPS and ICLR, as well as an associate editor of International Journal of Computer Vision.
Peng Gao is a research scientist at Shanghai Artificial Intelligence Laboratory, working on large language models and vision-language models. His research interests include vision-language models, large language models and diffusion models for contents creation. He has published more than 40 papers in top-tier journals and conferences, including International Journal of Computer Vision (IJCV), ICML, ICLR, NeurIPS, CVPR, ICCV and ECCV, receiving more than 10,000 citations. He has led several influential open-source projects including LLaMa-Adapter and the Lumina series, receiving more than 7000 and 2000 stars, respectively.


نقد و بررسیها
هنوز بررسیای ثبت نشده است.